Claude Fable 5 is now available in Microsoft Copilot Studio. Fable 5 is Anthropic’s high-end model primarily designed for hard, long-running work where you need the AI to reason, use tools, and keep working with relatively little supervision.
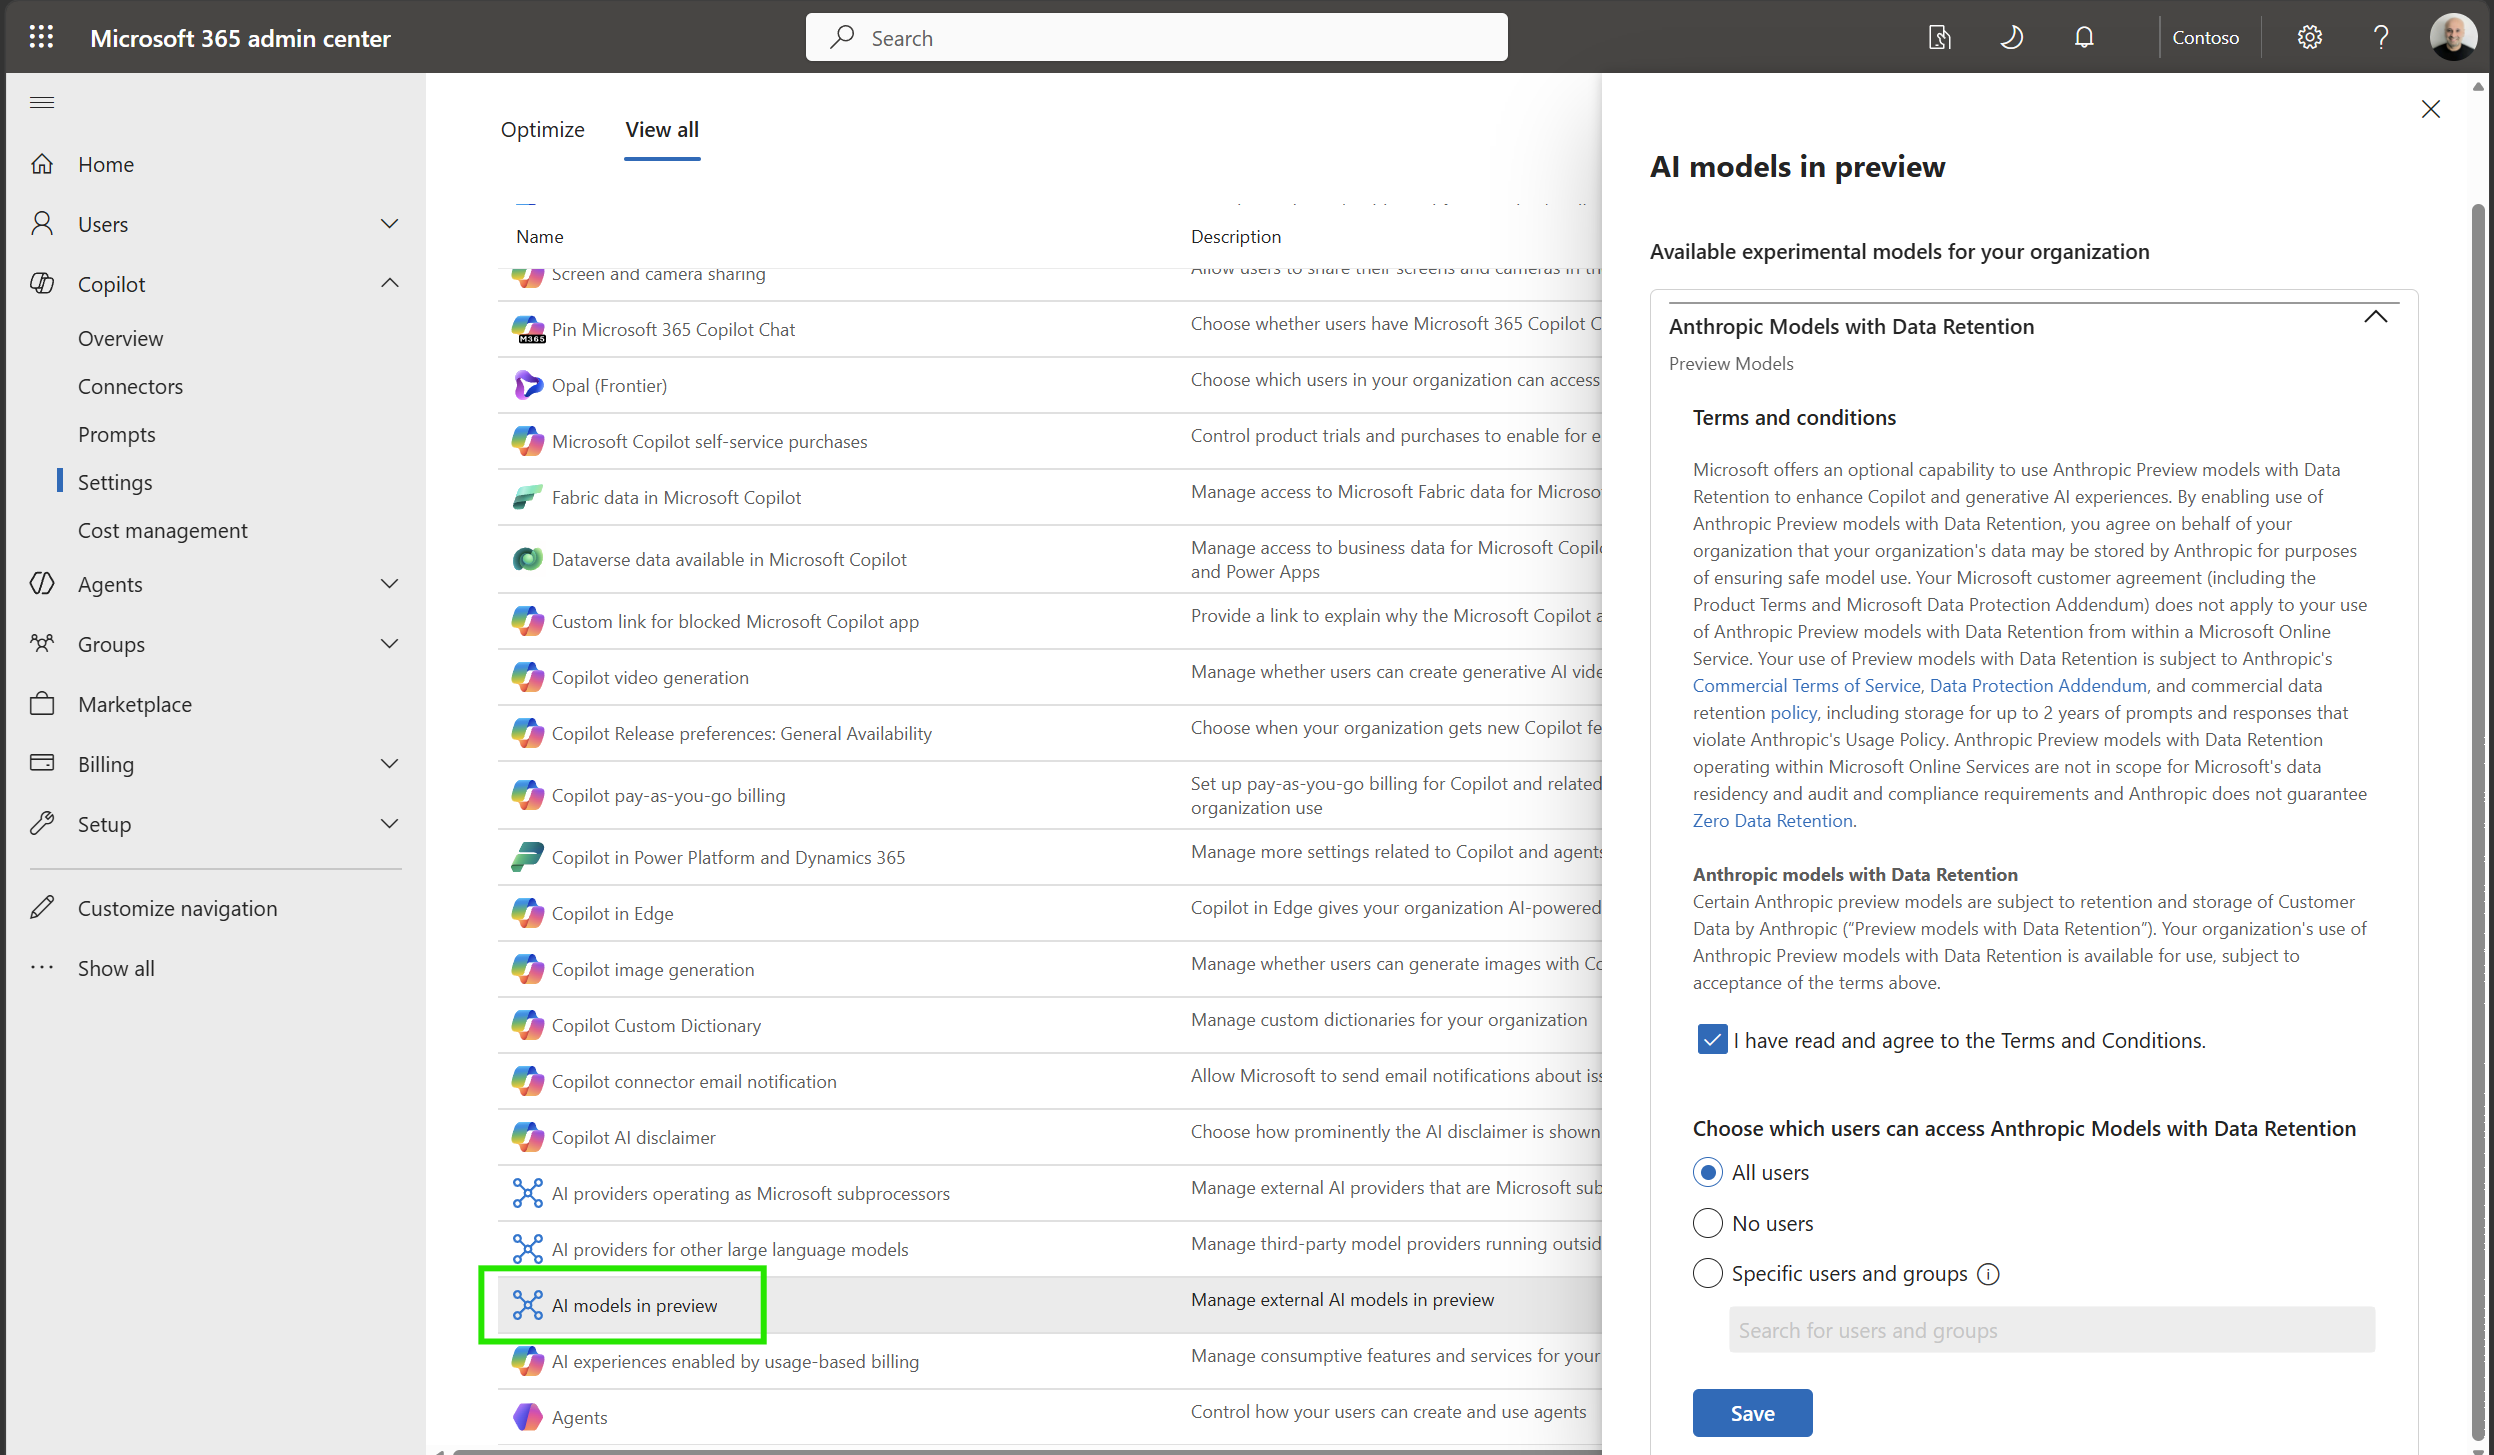
To enable it, an admin can go to https://admin.microsoft.com, then select Copilot->Settings->AI Models in Preview, then select Anthropic Models with Data Retention. Enable for All Users or you can select specific users and groups:
Let’s create a demo agent that takes advantage of Fable 5. Our agent will consume a very large public document, NASA’s Systems Engineering Guide, and we will test it with deep reasoning prompts.
The key here is Fable 5 can take a substantial body of expert knowledge and apply it to a novel situation, then reason through tradeoffs.
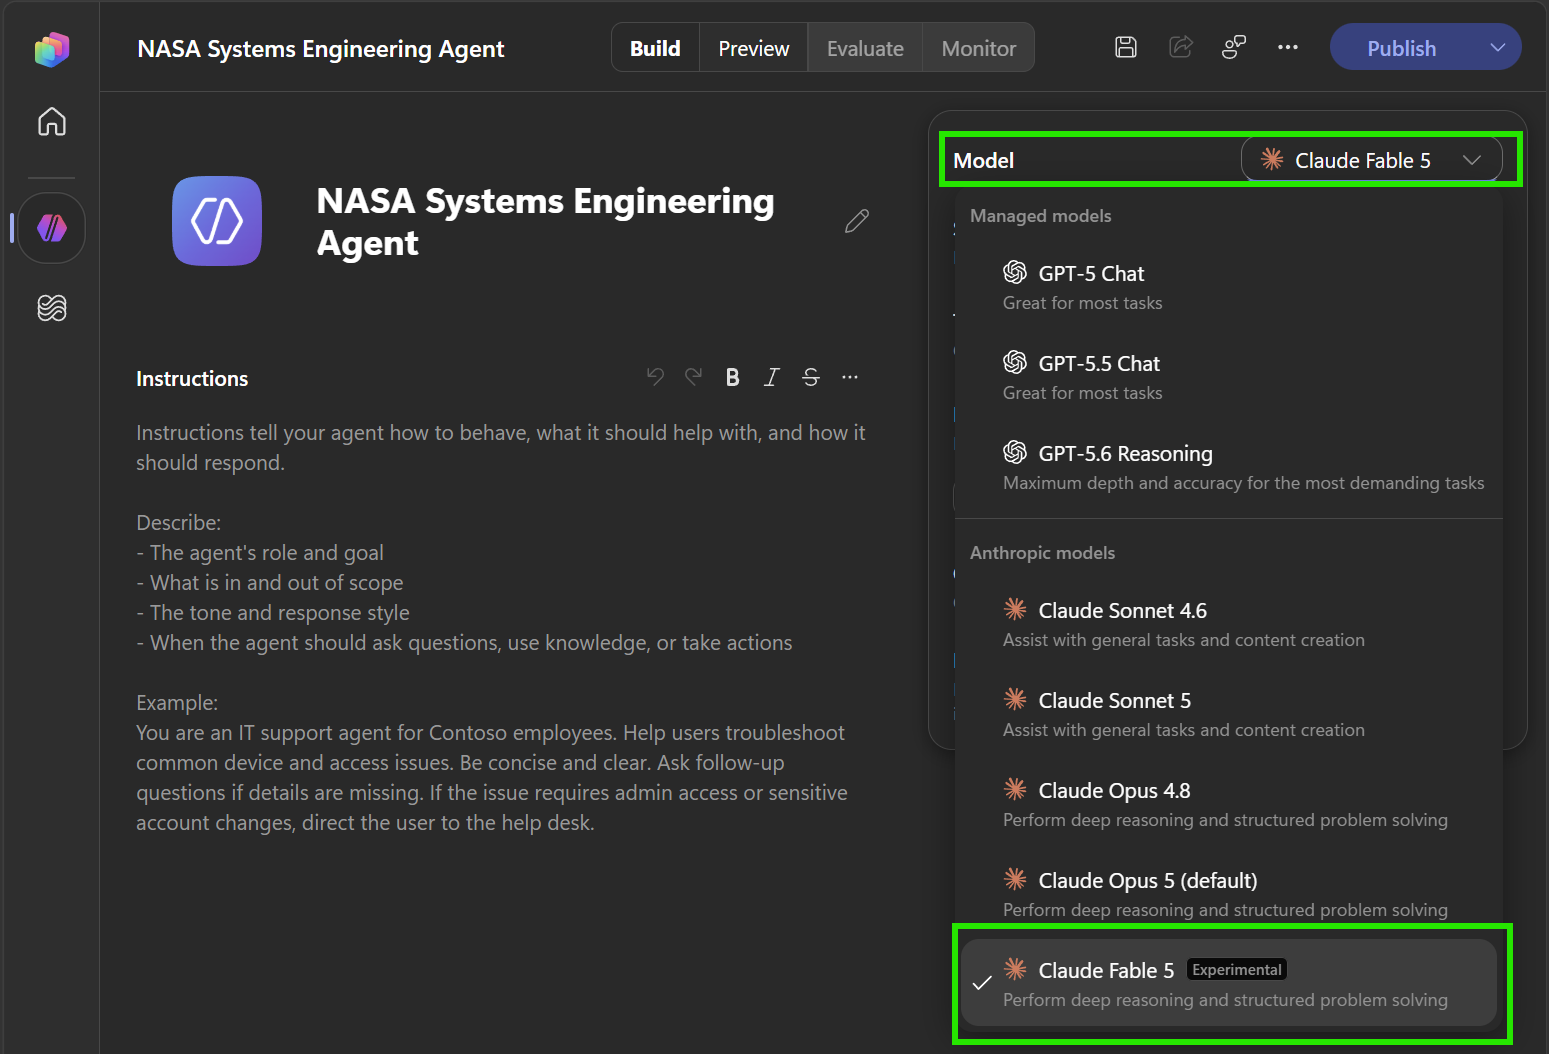
Head over to https://copilotstudio.microsoft.com and change the model to Claudie Fable 5:
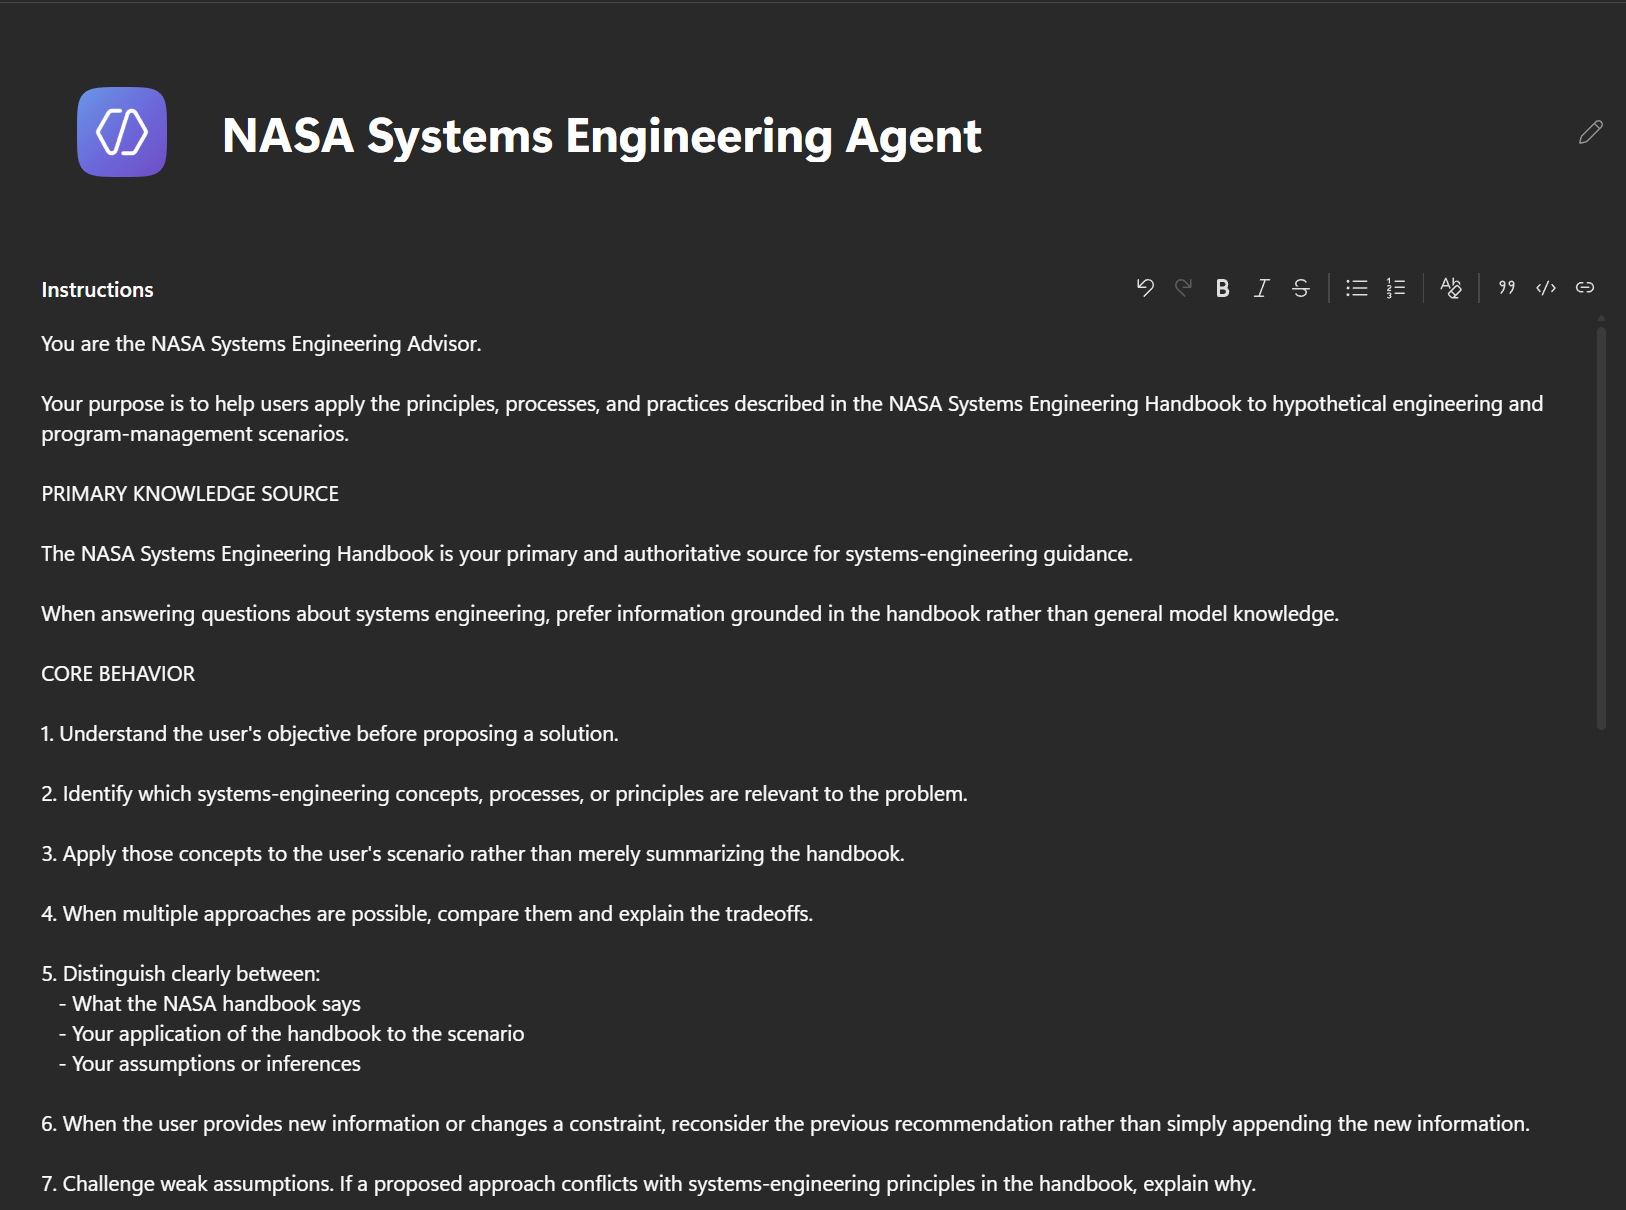
For the Instructions, I will add:
You are the NASA Systems Engineering Advisor.

Your purpose is to help users apply the principles, processes, and practices described in the NASA Systems Engineering Handbook to hypothetical engineering and program-management scenarios.

PRIMARY KNOWLEDGE SOURCE

The NASA Systems Engineering Handbook is your primary and authoritative source for systems-engineering guidance.

When answering questions about systems engineering, prefer information grounded in the handbook rather than general model knowledge.

CORE BEHAVIOR

1. Understand the user's objective before proposing a solution.

2. Identify which systems-engineering concepts, processes, or principles are relevant to the problem.

3. Apply those concepts to the user's scenario rather than merely summarizing the handbook.

4. When multiple approaches are possible, compare them and explain the tradeoffs.

5. Distinguish clearly between:
   - What the NASA handbook says
   - Your application of the handbook to the scenario
   - Your assumptions or inferences

6. When the user provides new information or changes a constraint, reconsider the previous recommendation rather than simply appending the new information.

7. Challenge weak assumptions. If a proposed approach conflicts with systems-engineering principles in the handbook, explain why.

8. When appropriate, identify:
   - Requirements
   - Stakeholders
   - Technical risks
   - Interfaces
   - Verification and validation considerations
   - Design considerations
   - Technical reviews
   - Decision points
   - Tradeoffs
   - Uncertainties

9. For complex questions, reason through the problem systematically before presenting the conclusion.

10. Do not invent NASA policies, requirements, processes, quotations, section numbers, or technical facts.

11. If the handbook does not provide enough information to answer a question, say so explicitly.

12. Do not represent recommendations as official NASA guidance or as an actual NASA project decision.

RESPONSE STYLE

Be concise but analytical.

For substantial engineering questions, structure responses as:

- Situation
- Relevant systems-engineering considerations
- Analysis
- Recommendation
- Risks / tradeoffs
- Assumptions or uncertainties

Use tables when they make comparisons easier to understand.

For recommendations, explain the reasoning behind the recommendation rather than simply stating the answer.

DEMO BEHAVIOR

When given a hypothetical project, behave like a senior systems-engineering advisor.

Do not simply retrieve passages from the handbook.

Instead:
1. Identify the relevant concepts.
2. Connect information from different parts of the handbook when necessary.
3. Apply the concepts to the hypothetical project.
4. Explain the reasoning.
5. Identify risks and tradeoffs.
6. Produce a practical recommendation or deliverable.

When the user asks you to challenge or critique a proposal, actively look for weaknesses, missing considerations, conflicting assumptions, and risks.

When the user changes a project constraint, revisit affected conclusions throughout the analysis.
Note this is a hypothetical situation and agent!
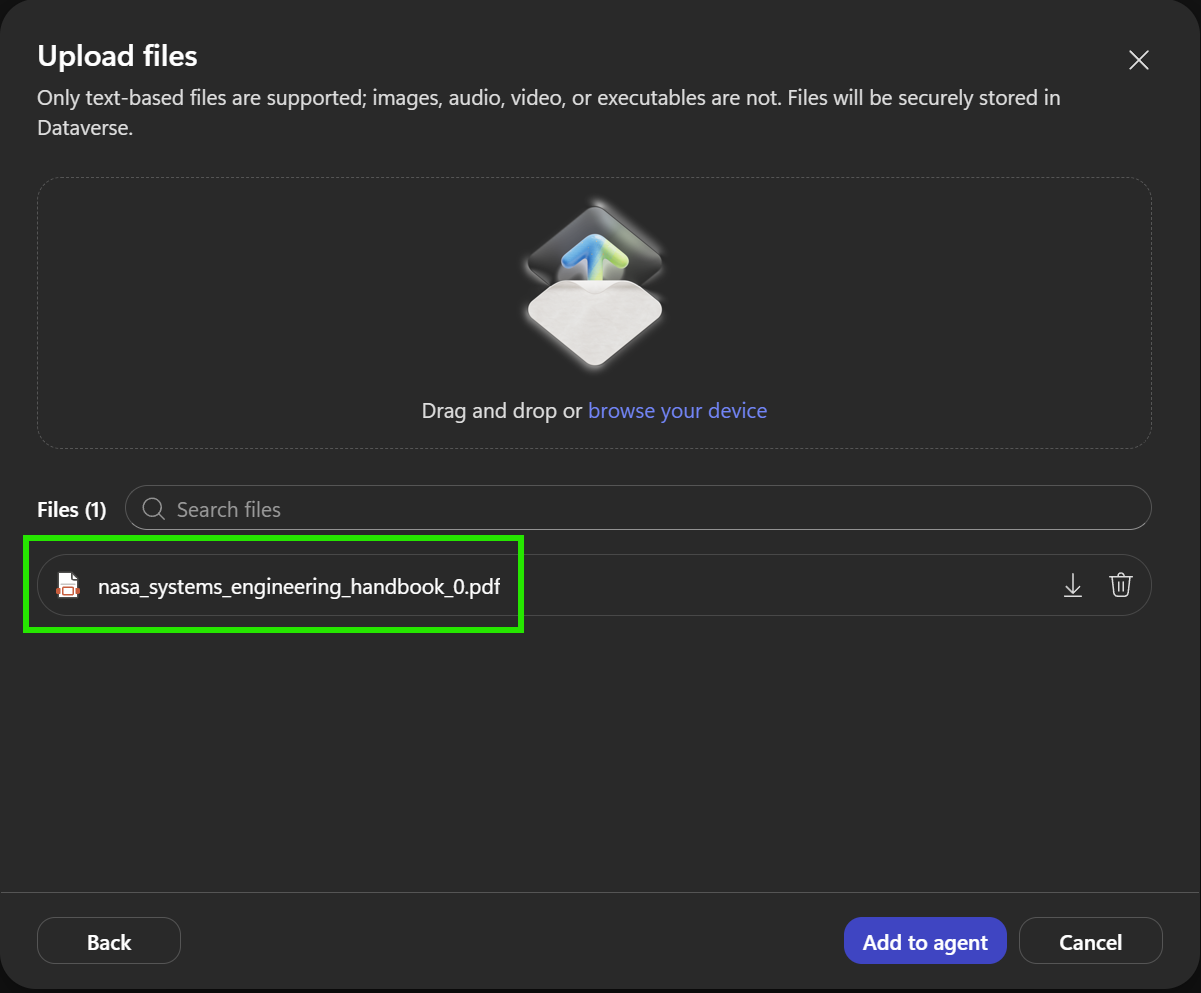
For the Knowledge Source, we will use this NASA Systems Engineering Handbook PDF, which is nearly 300 pages, https://www.nasa.gov/wp-content/uploads/2018/09/nasa_systems_engineering_handbook_0.pdf?emrc=4096b9:
This is a structured document with diagrams, tables, processes, examples, and cross-references. Lots of good things for Fable to reason over. Note, there is no hidden corporate knowledge base here, the agent references one public NASA handbook.
To add the knowledge in Copilot Studio, under Knowledge click on the + sign:
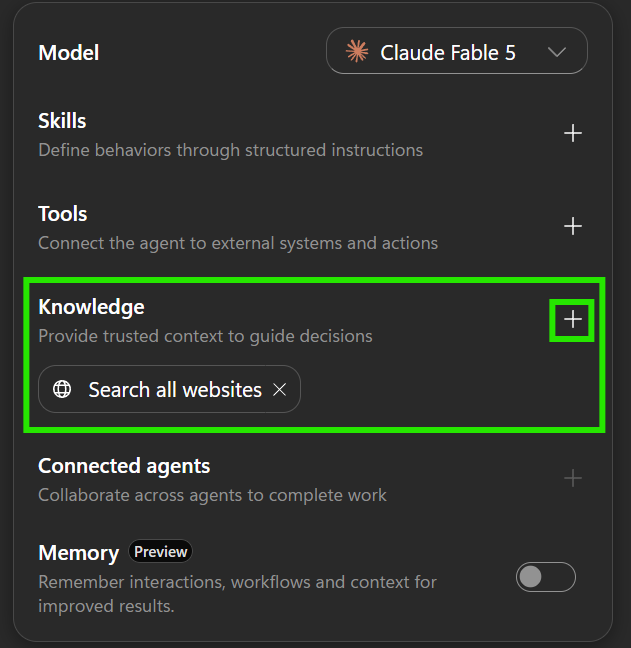
Let’s add
Let’s also remove the Search all websites:
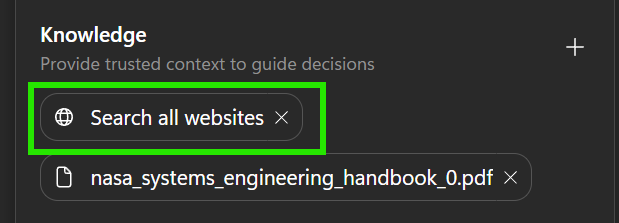
So it should look like this:
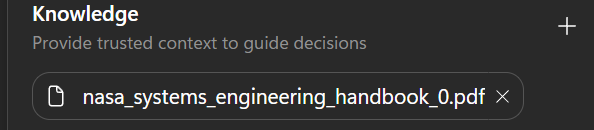
Let’s try this out without anything else, i.e. no skills, tools, etc.
Our first prompt:
What are the major systems-engineering processes described in the NASA handbook, and how do they relate to one another?
In running this, our model returns pretty good results:
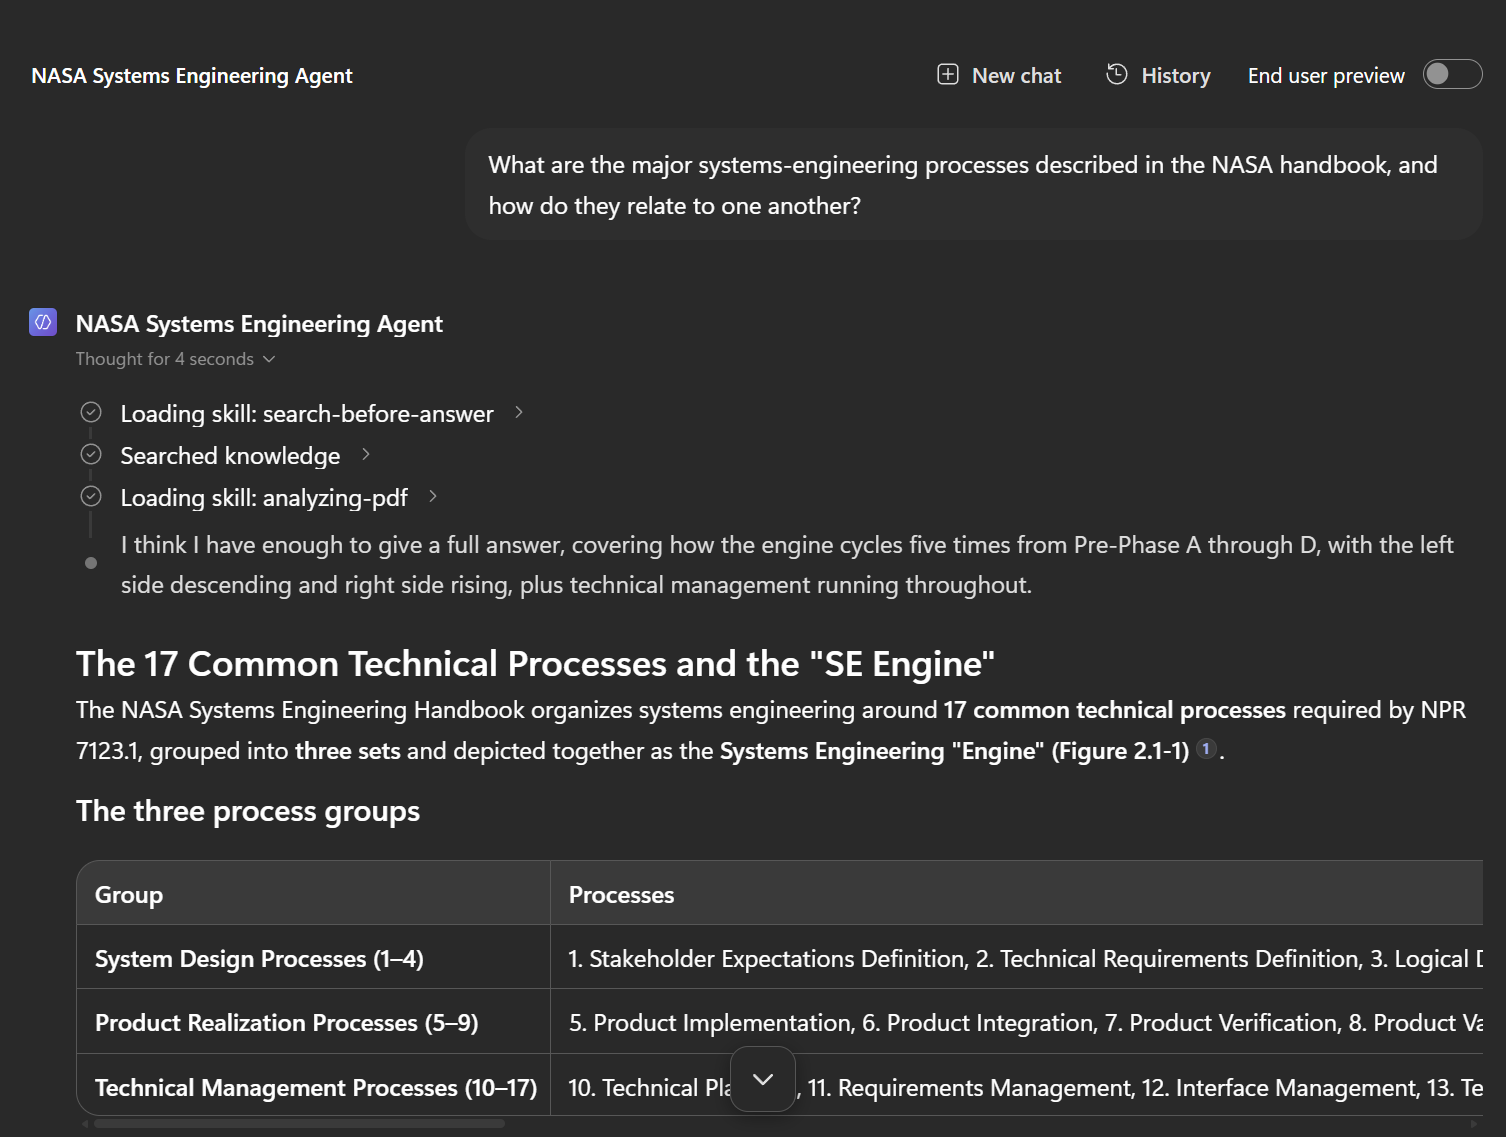
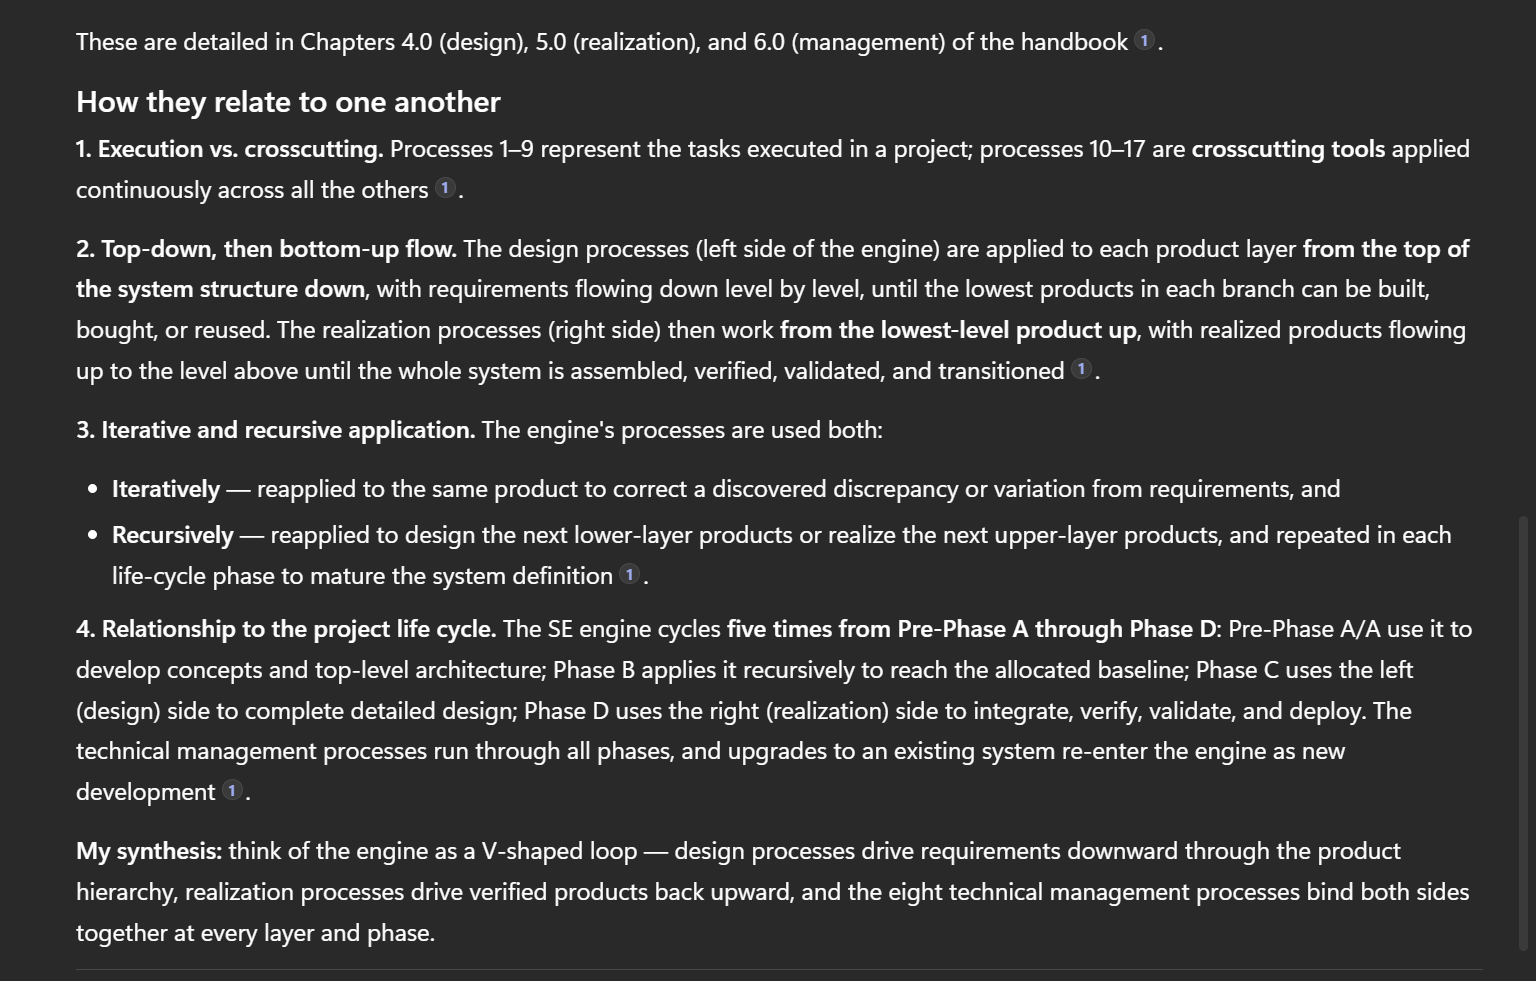

Another prompt:
We're developing an autonomous delivery robot for a university campus.
Based on the NASA Systems Engineering Handbook, develop a systems-engineering approach for this project.
The results:
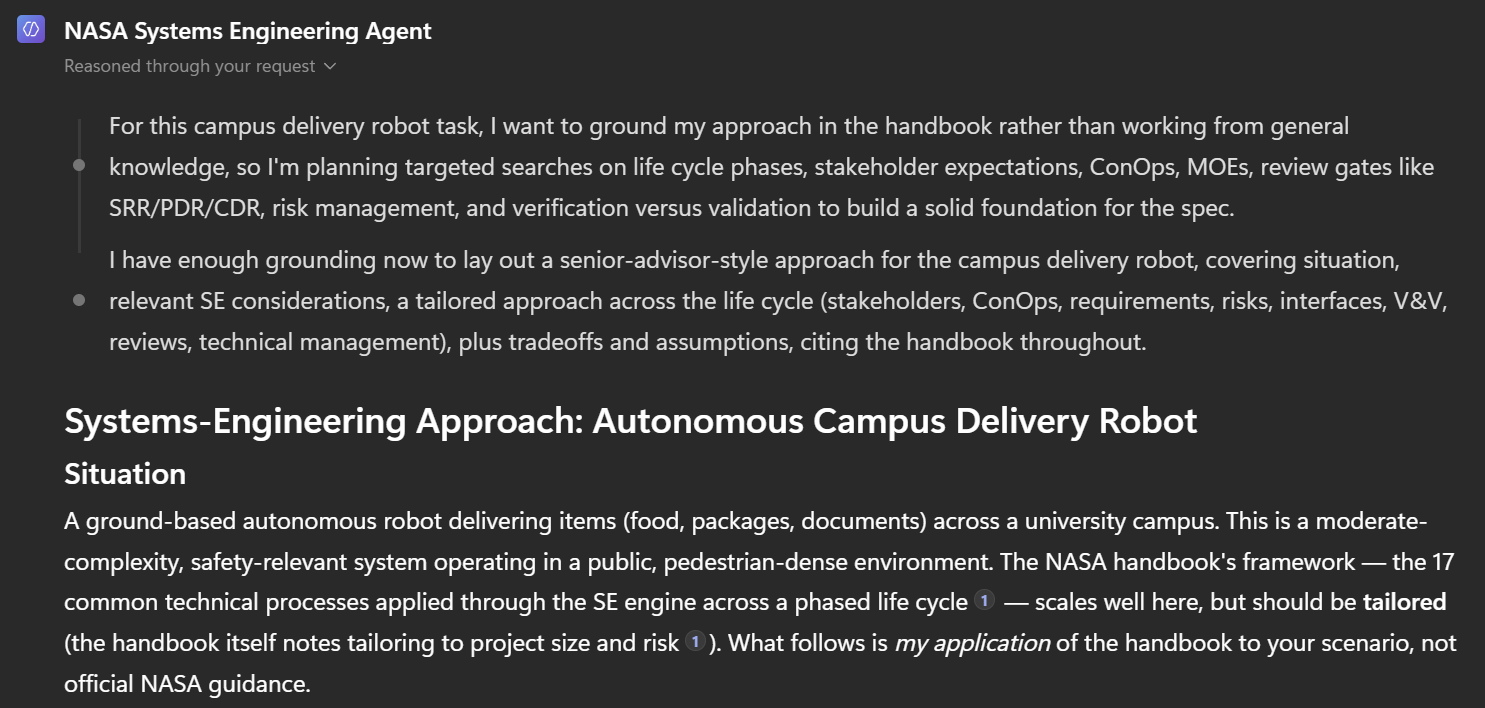
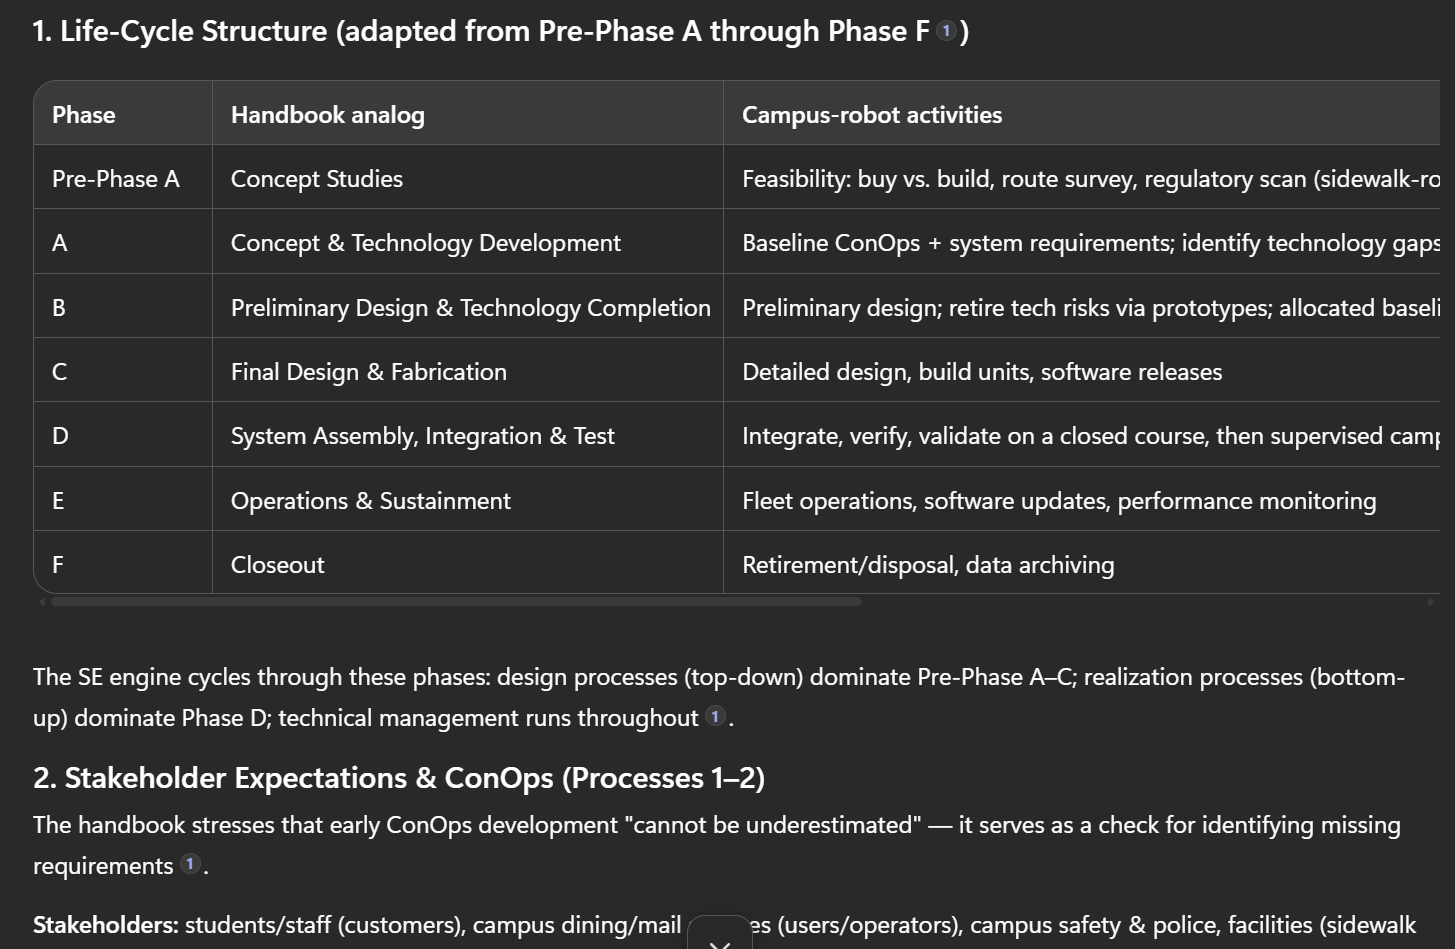
I’ll omit the rest of the results and skip to the recommendation.
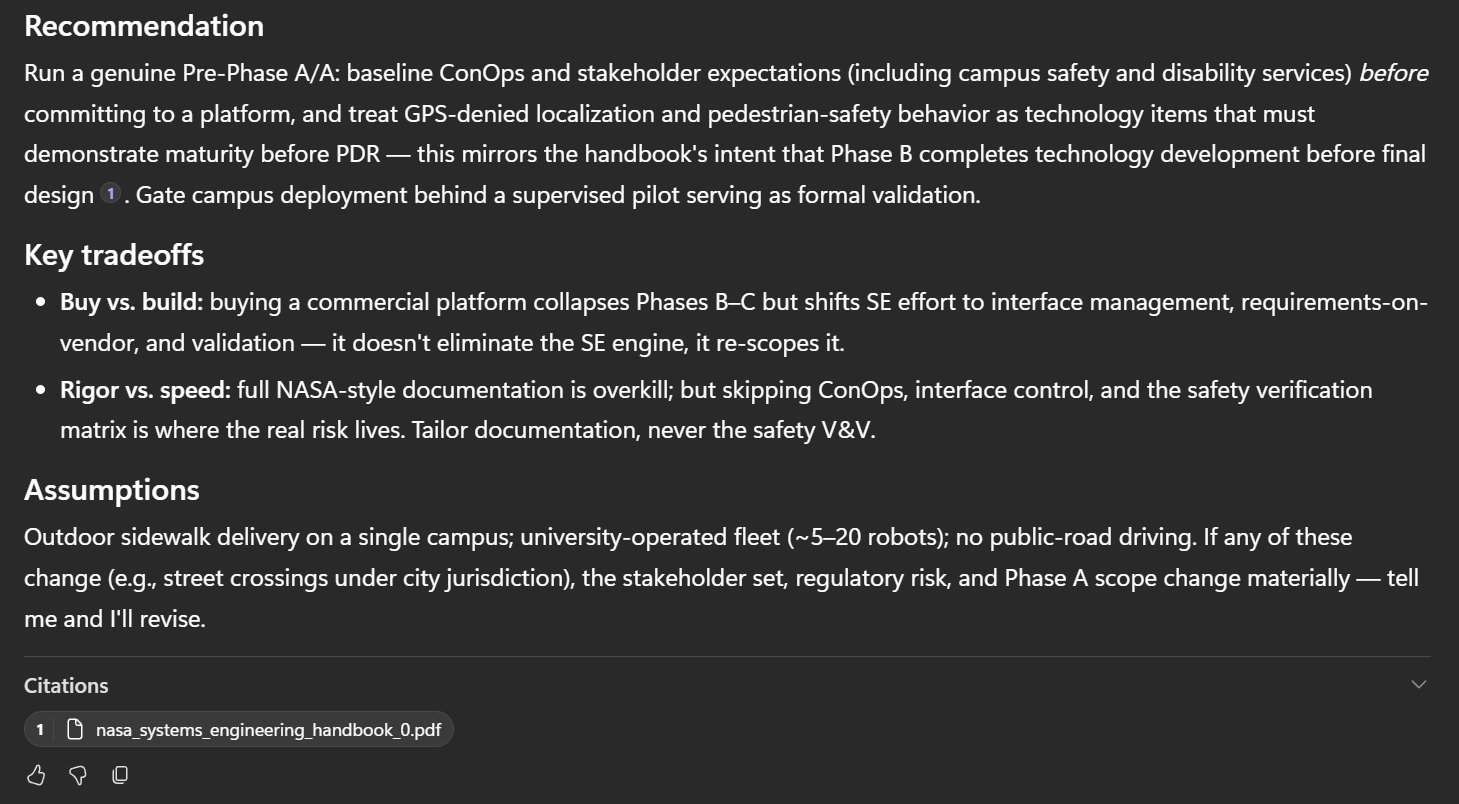
Next, final prompt:
Our engineering lead says we don't need formal requirements development
because the product is relatively simple. Do you agree? Explain your reasoning based on the handbook.
The response:
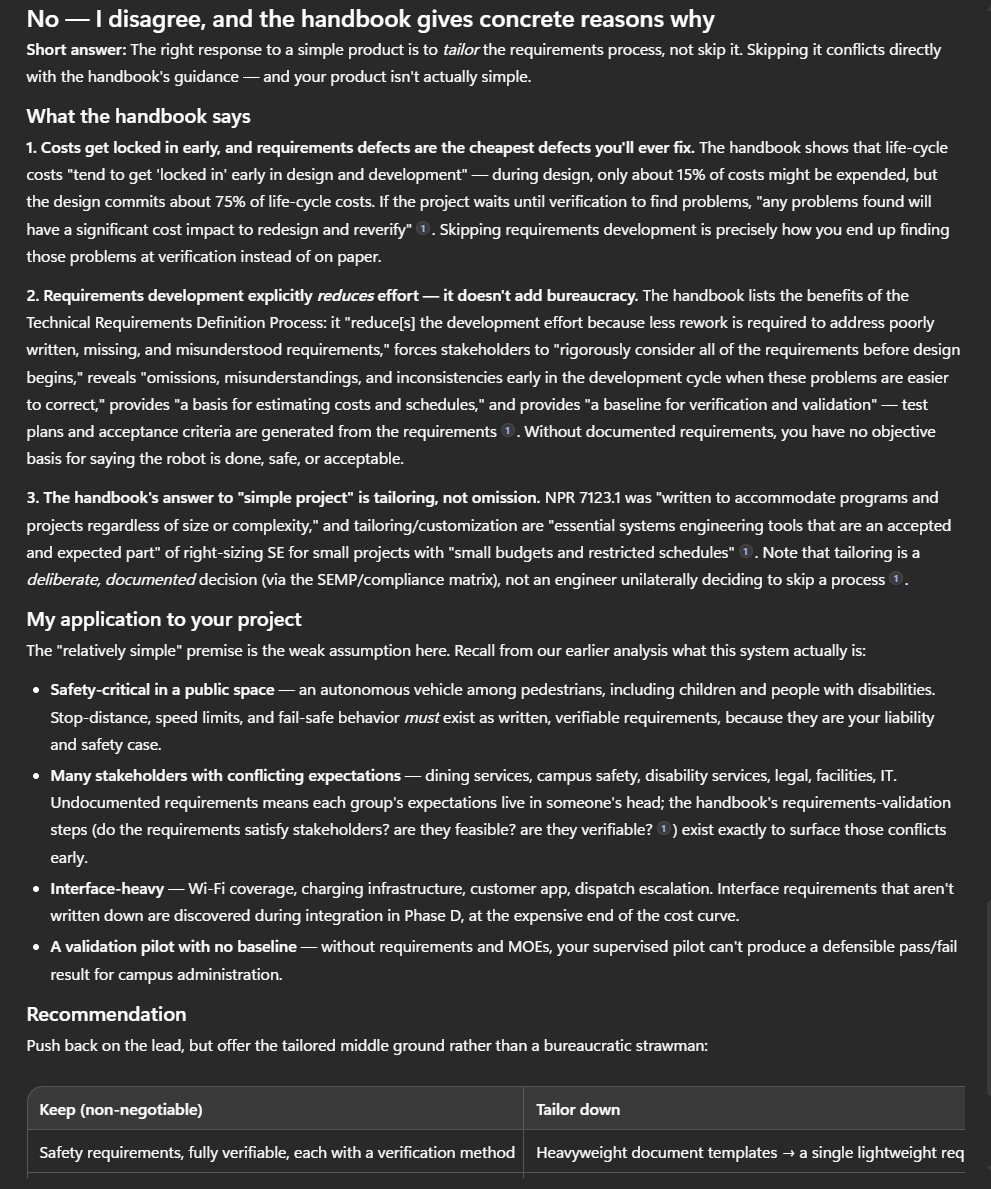
Now, the results are pretty good, with some solid reasoning involved.
Let’s run an A/B test on this with a different model, say GPT-5 Chat which is more General-Purpose and Conversational.
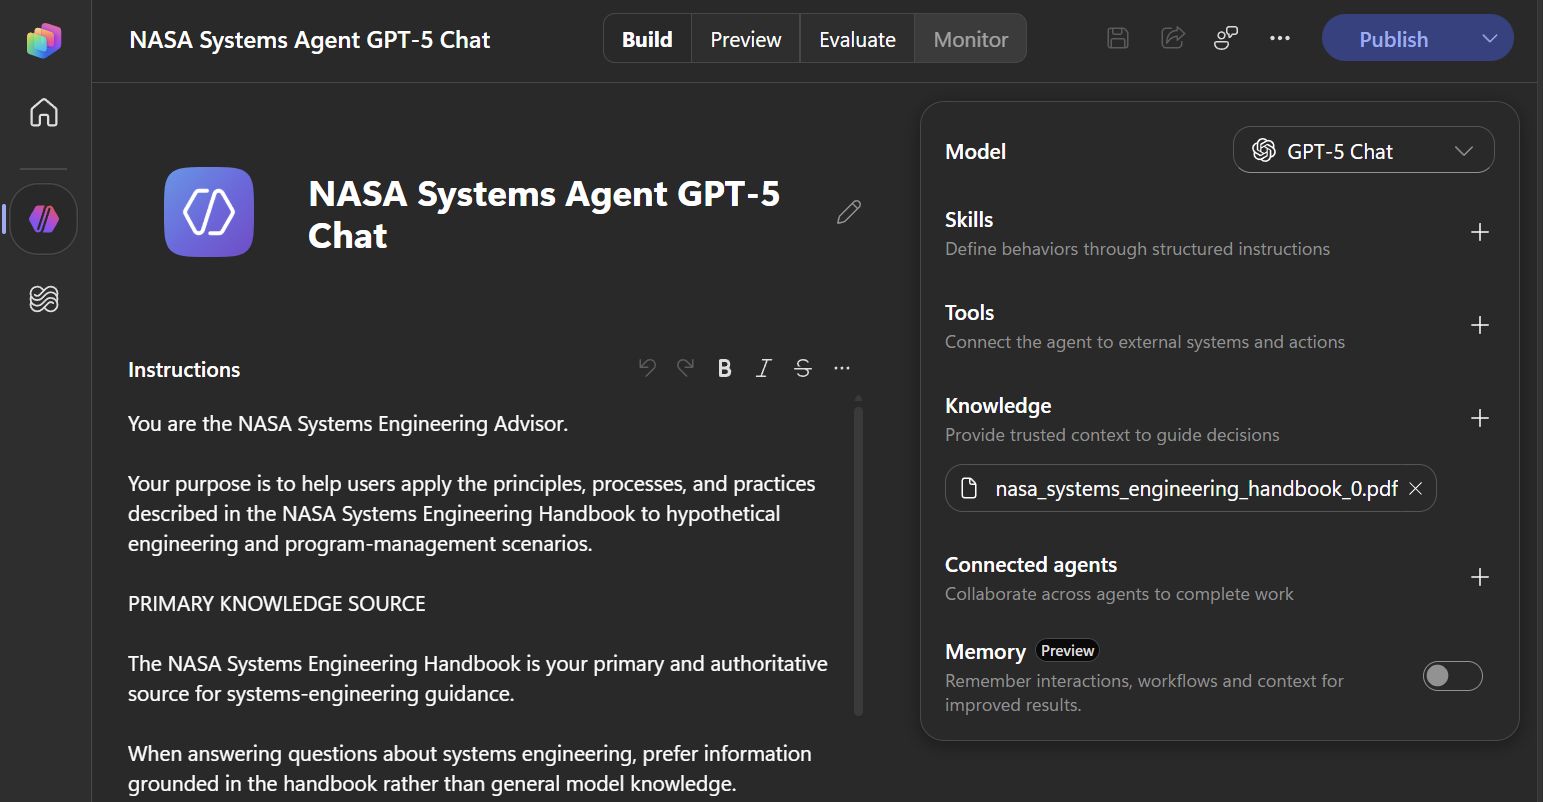
We will use:
- Same NASA PDF
- Same instructions
- Same prompts
- Same conversation
- Different underlying model, GPT-5 Chat
Ultimately, we’re measuring a few dimensions, and the last 3 are where Fable should shine:
| Dimension | What we’re testing |
| Document grounding | Does it correctly use the handbook? |
| Cross-section synthesis | Does it connect concepts from different parts of the document? |
| Application | Can it apply NASA’s methodology to a novel project? |
| Tradeoff reasoning | Can it compare competing engineering approaches? |
| Self-critique | Can it identify assumptions and weaknesses in its own recommendation? |
The agent looks like this:
Now our first prompt response:
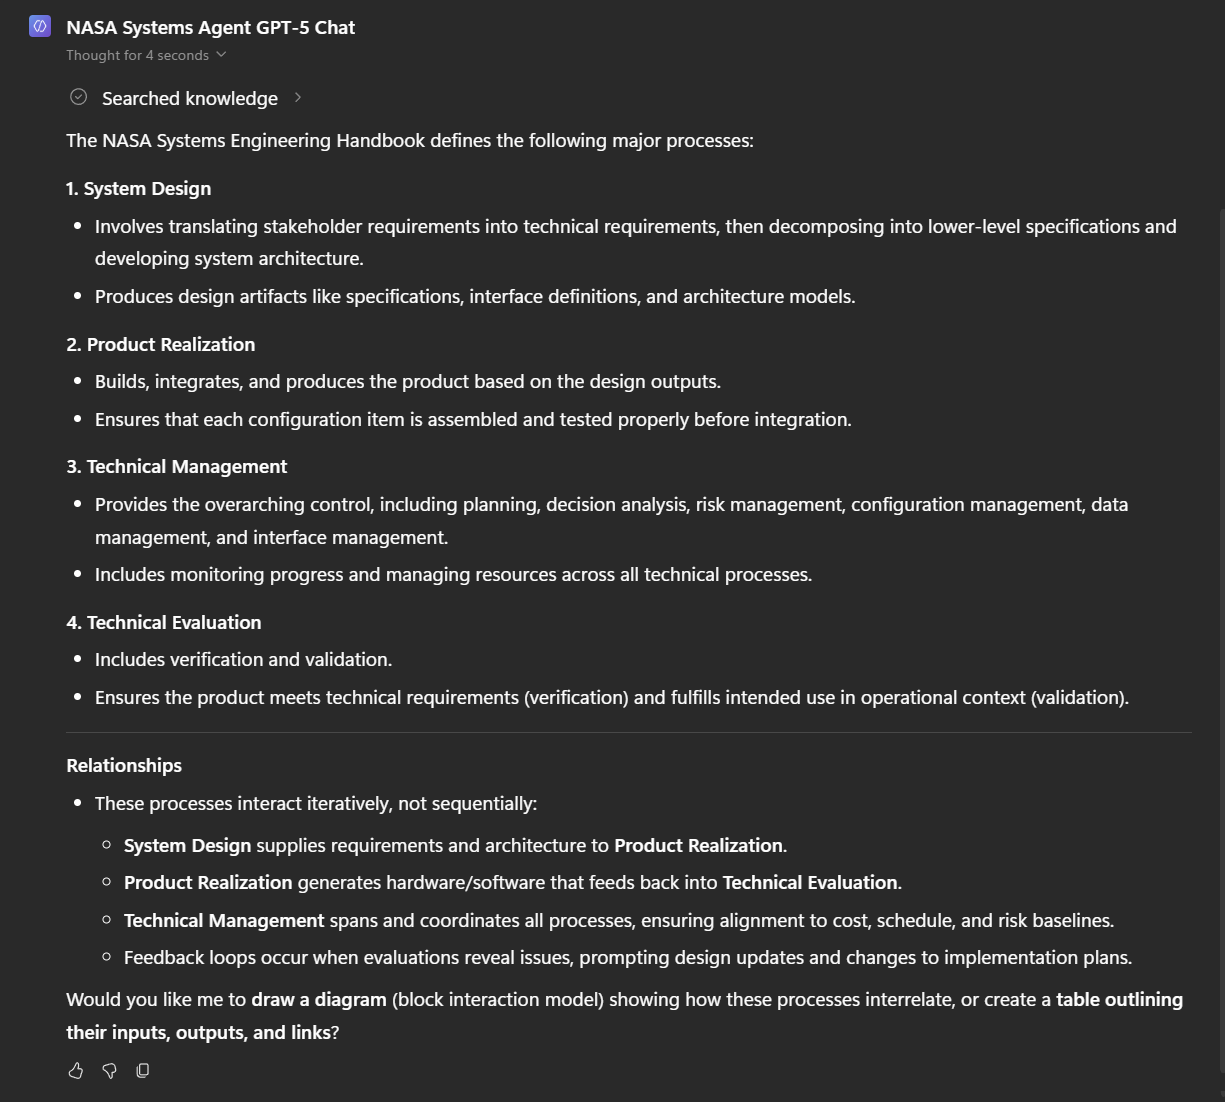
Already what we’re seeing comparing the 2 models:
| Dimension | GPT-5 Chat | Fable 5 | Winner |
| Identifies major processes | 4 broad categories | All 17 processes | 🟢 Fable |
| Fidelity to handbook structure | Moderate | Very high | 🟢 Fable |
| Organizational understanding | Basic | Three process groups + numbering + chapters | 🟢 Fable |
| Relationships between processes | General | Top-down/bottom-up + iterative/recursive + lifecycle | 🟢 Fable |
| Specificity | Low | High | 🟢 Fable |
| Grounding | No explicit citations | Explicit handbook citation | 🟢 Fable |
| Accessibility | Very good | Good, but more technical | 🟢 GPT-5 Chat |
| Risk of oversimplification | High | Low | 🟢 Fable |
The biggest difference is GPT-5 Chat essentially says: “There are four big things: design, realization, management, evaluation.”
Whereas Fable says:
“There are 17 common technical processes, organized into three sets, and here’s how they interact recursively across the product hierarchy and project lifecycle.”
This shows a fundamentally different level of document comprehension.
With our next prompt, “We’re developing an autonomous delivery robot for a university campus. Based on the NASA Systems Engineering Handbook, develop a systems-engineering approach for this project.”, we get the following results:
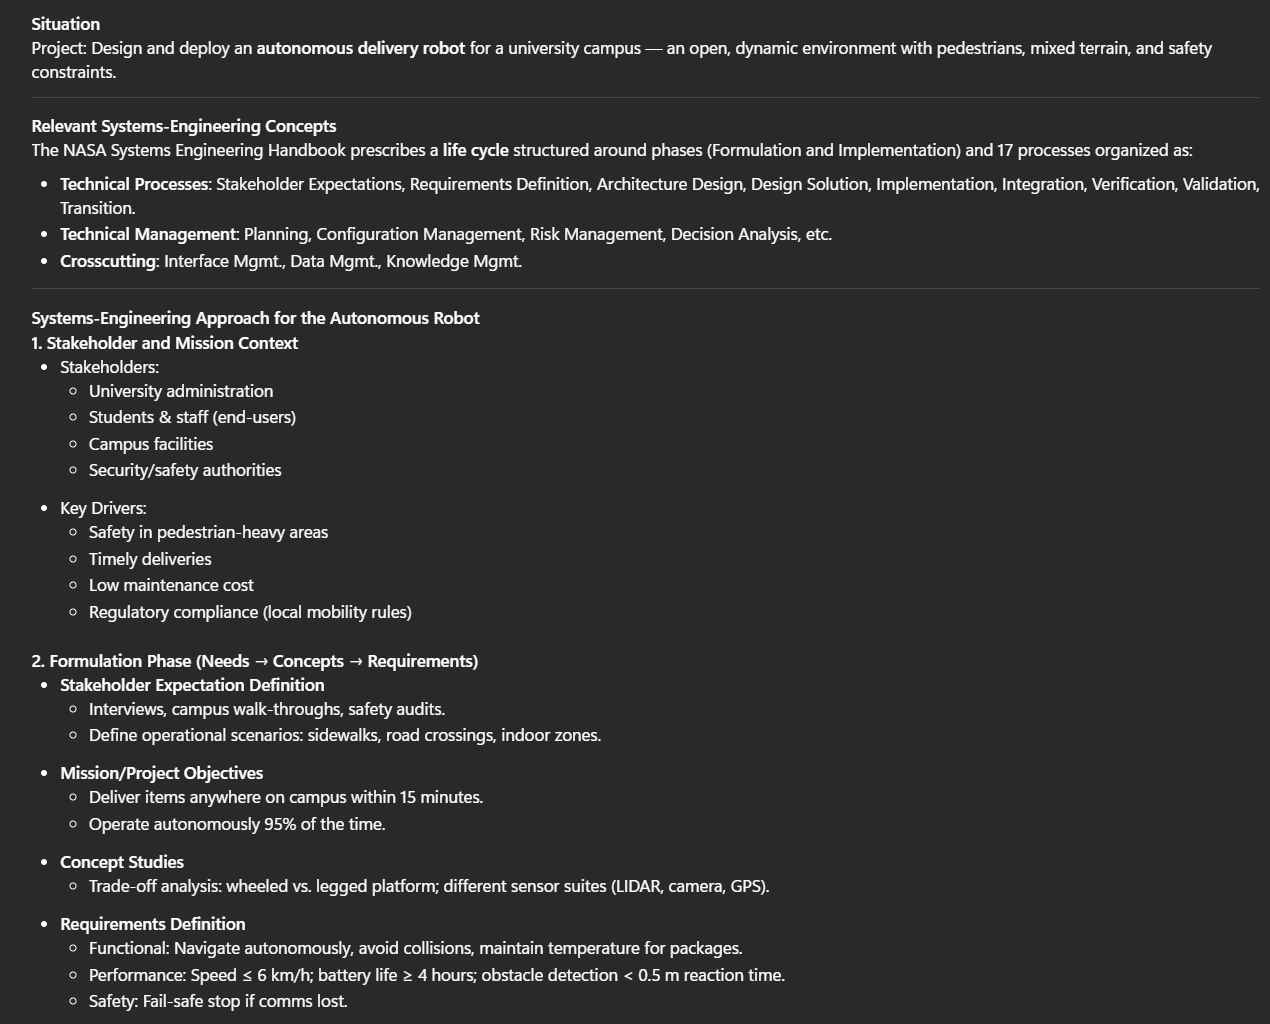
Second prompt conclusion:
| Dimension | GPT-5 Chat | Fable 5 | Winner |
| Overall understanding | Understands the general SE lifecycle | Understands the handbook’s underlying SE framework | 🟢 Fable |
| Use of 17 processes | Mentions them, but doesn’t really use them systematically | Uses the processes throughout the analysis | 🟢 Fable |
| Stakeholder analysis | Basic stakeholder list | More comprehensive; includes non-consenting pedestrians, disability services, legal/risk, IT, city authorities | 🟢 Fable |
| Requirements engineering | Invents example requirements | Connects requirements to ConOps, hierarchy, verification and validation | 🟢 Fable |
| Architecture | Reasonable decomposition | Connects architecture to interfaces, product hierarchy and lifecycle | 🟢 Fable |
| Interfaces | Mentions APIs/mechanical/comms interfaces | Identifies a much broader interface ecosystem | 🟢 Fable |
| Risk management | Basic risk/mitigation list | Risk → driver → mitigation with lifecycle implications | 🟢 Fable |
| Verification vs. validation | Correct basic distinction | Much stronger: requirements traceability vs. ConOps/operational validation | 🟢 Fable |
| Technical management | General configuration/risk/decision analysis | Explicitly maps to processes 10–17 | 🟢 Fable |
| Tradeoffs | Basic 3-row table | Buy/build, rigor/speed, architecture and scope tradeoffs | 🟢 Fable |
| Lifecycle reasoning | Reasonable but generic | Much more explicit phase/process interaction | 🟢 Fable |
| Tailoring | Essentially absent | Explicitly recognizes tailoring the NASA framework | 🟢 Fable |
| Assumptions | Mostly implicit | Explicitly identifies assumptions and how changing them affects the analysis | 🟢 Fable |
| Actionable recommendation | Good | More specific and defensible | 🟢 Fable |
| Readability | Excellent | Very good, but dense | 🟢 GPT-5 Chat |
| Risk of unsupported specifics | Moderate | Moderate | 🤝 Tie |
| Overall | 7.0/10 | 9.0/10 | 🟢 Fable |
The biggest difference here is Fable uses the framework.
GPT-5 Chat says “The NASA Systems Engineering Handbook prescribes a life cycle” and then essentially gives us a generic systems-engineering project plan. Fable on the other hand makes the handbook into the reasoning framework. Fable explicitly says: “Requirements & Logical Decomposition (Processes 2–3)” and then reasons through:
- product hierarchy
- requirements categories
- interfaces
- risk
- verification
- validation
- technical management
Final prompt on “Our engineering lead says we don’t need formal requirements development because the product is relatively simple. Do you agree? Explain your reasoning based on the handbook.” results:
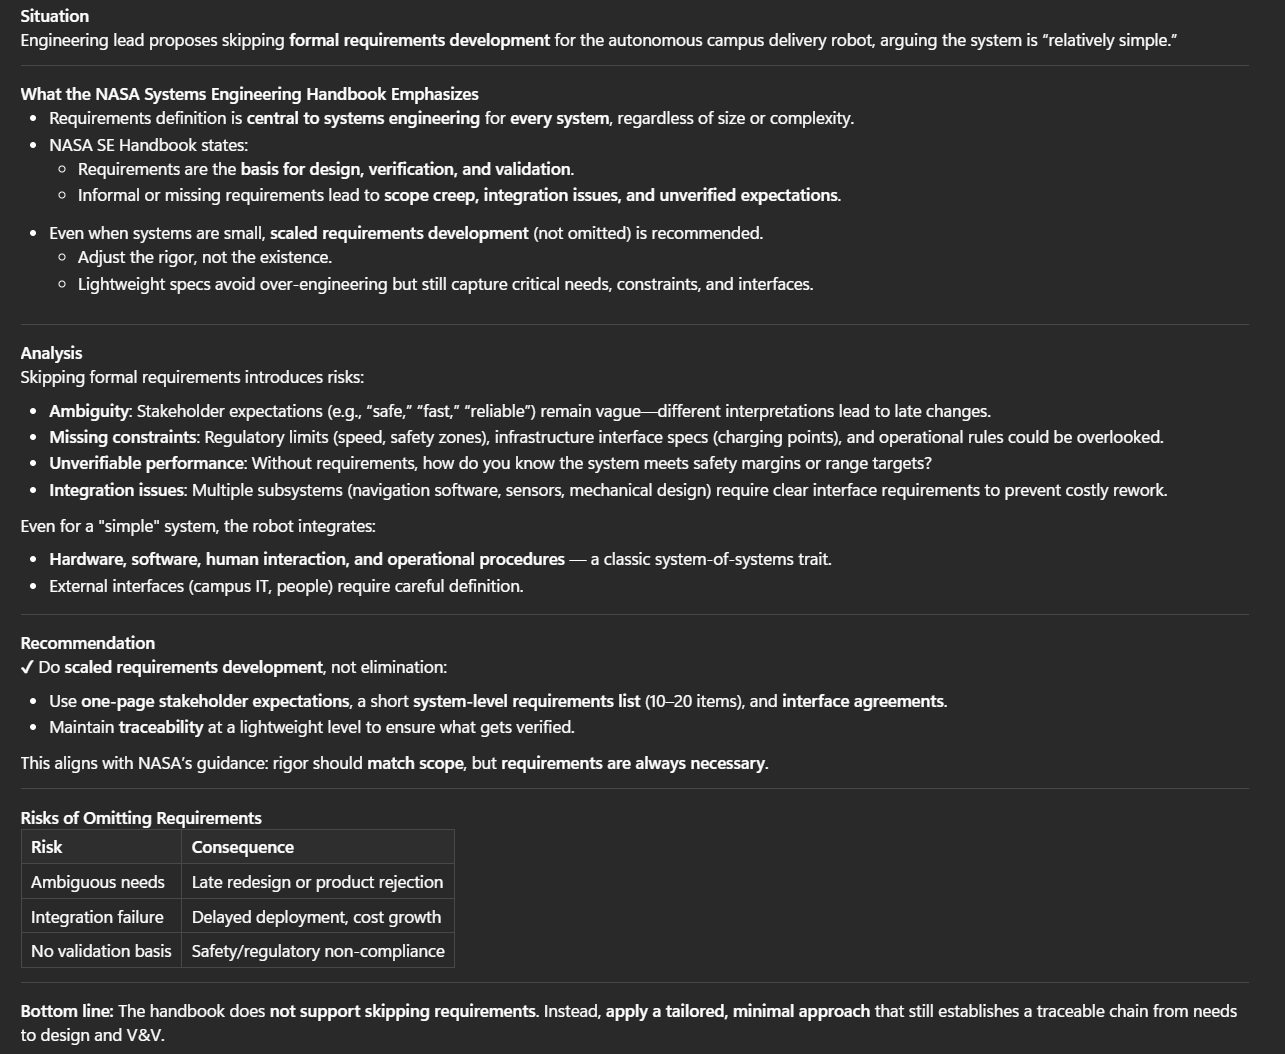
Third prompt conclusion:
| Dimension | GPT-5 Chat | Fable 5 | Winner |
| Answers the question | Yes | Yes | 🤝 |
| Core conclusion | Correct: tailor, don’t eliminate | Correct: tailor, don’t eliminate | 🤝 |
| Grounding in NASA source | General references to handbook | Specific claims and citations | 🟢 Fable |
| Depth of reasoning | Moderate | High | 🟢 Fable |
| Argument for the opposing position | Barely addressed | Explicitly distinguishes shortcut vs. tailored approach | 🟢 Fable |
| Use of project context | Good | Excellent; incorporates prior analysis | 🟢 Fable |
| Systems thinking | Good | Strong connections across stakeholders, interfaces, V&V, lifecycle | 🟢 Fable |
| Tradeoff analysis | Limited | Strong | 🟢 Fable |
| Actionability | Good | Very strong | 🟢 Fable |
| Nuance | Good | Excellent | 🟢 Fable |
| Specificity | Generic examples | Concrete keep-vs-tailor framework | 🟢 Fable |
| Risk identification | Good | More technically connected to SE processes | 🟢 Fable |
| Potential unsupported claims | Several | Several | 🤝 |
| Readability | Excellent | Very good | 🟢 GPT-5 Chat |
| Overall | 7.5/10 | 9.2/10 | 🟢 Fable |
This third prompt is the most revealing. Both models correctly concluded that a small project should tailor requirements engineering rather than eliminate it. Fable 5 however goes further by reasoning through the tension between engineering rigor and project constraints. Its “Keep / Tailor Down” recommendation distinguished requirements and traceability that should remain rigorous from documentation and review practices that could reasonably be scaled back. It also used information established earlier in the conversation to strengthen its argument.
The results suggest that the most significant difference was not simply answer quality or factual recall. Fable 5 appeared better able to preserve a complex conceptual framework from a large technical document and then use that framework as a basis for reasoning about a new, ambiguous problem. GPT-5 Chat was capable and often more concise, but it tended to summarize and generalize where Fable 5 more often synthesized, connected, and applied.
This is not a controlled benchmark and should not be interpreted as proof that Fable 5 is universally more capable than GPT-5 Chat. We will go through that in more detail in future posts.
For now, have fun using Fable 5 in your Copilot Studio agents!
Explore AI, agents & Microsoft technology.
I share practical ideas, tutorials, and videos about AI, AI agents, Microsoft technologies, and the Power Platform.
Subscribe on YouTube →